Blog 6 posts

01.

I benchmarked Jev's box tool on ScreenSpot-v2 and ScreenSpot-Pro. Here is how well it reads a screen

Can Jev's new box tool find what your agent needs to click? On ScreenSpot it hits 84% on normal screens and 19% in 4K pro apps. Zooming in on its first answer takes Pro to 43%, for $0.32 per 1,000 clicks.

· 12 min read
02.

Why computer use benchmarks are so hard to run

Running a computer use benchmark like OSWorld is easy to start and hard to get right. I read about 200 GitHub issues to see what goes wrong. Here are the 10 problems you will face, and how I would handle each.

· 17 min read

03.

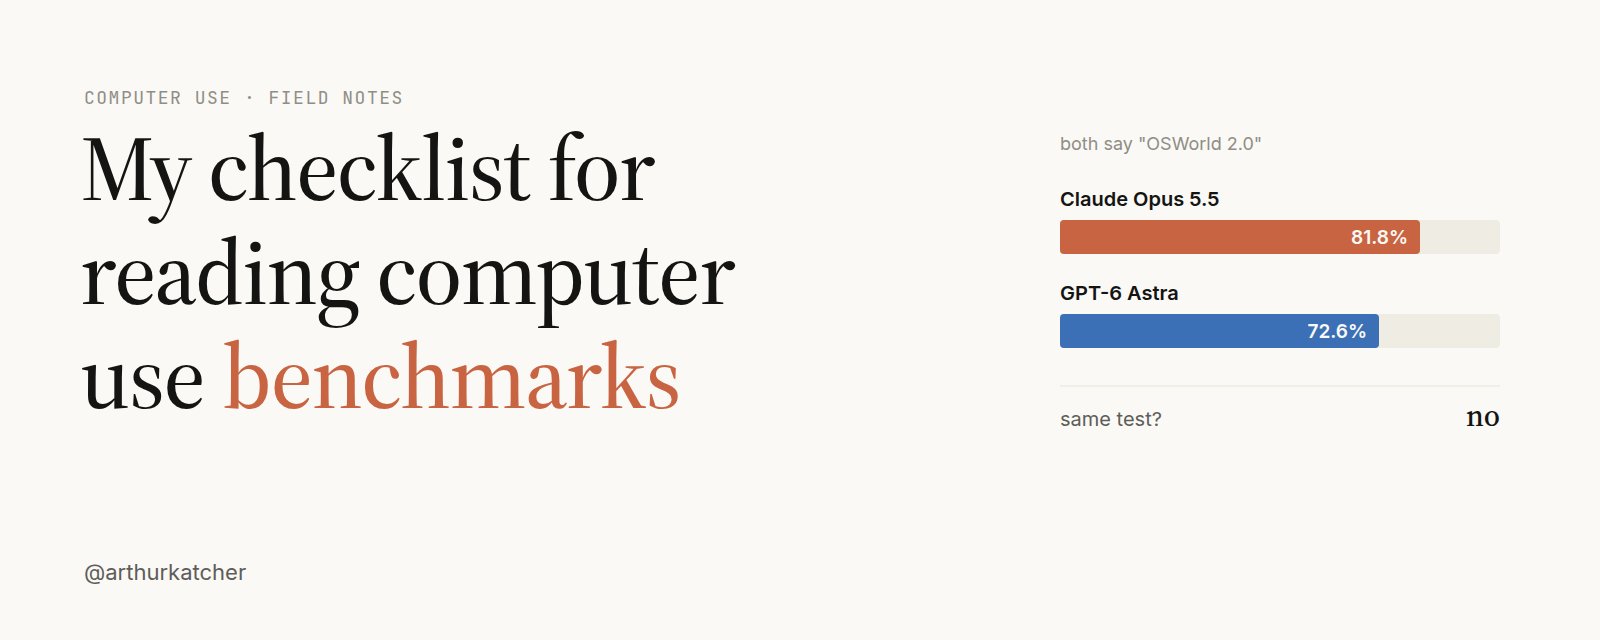
My checklist for reading computer use benchmarks

I read about 40 benchmark repositories and 230 sources to understand computer use scores. I came out with six questions I now ask before I believe any of them.

· 16 min read

04.

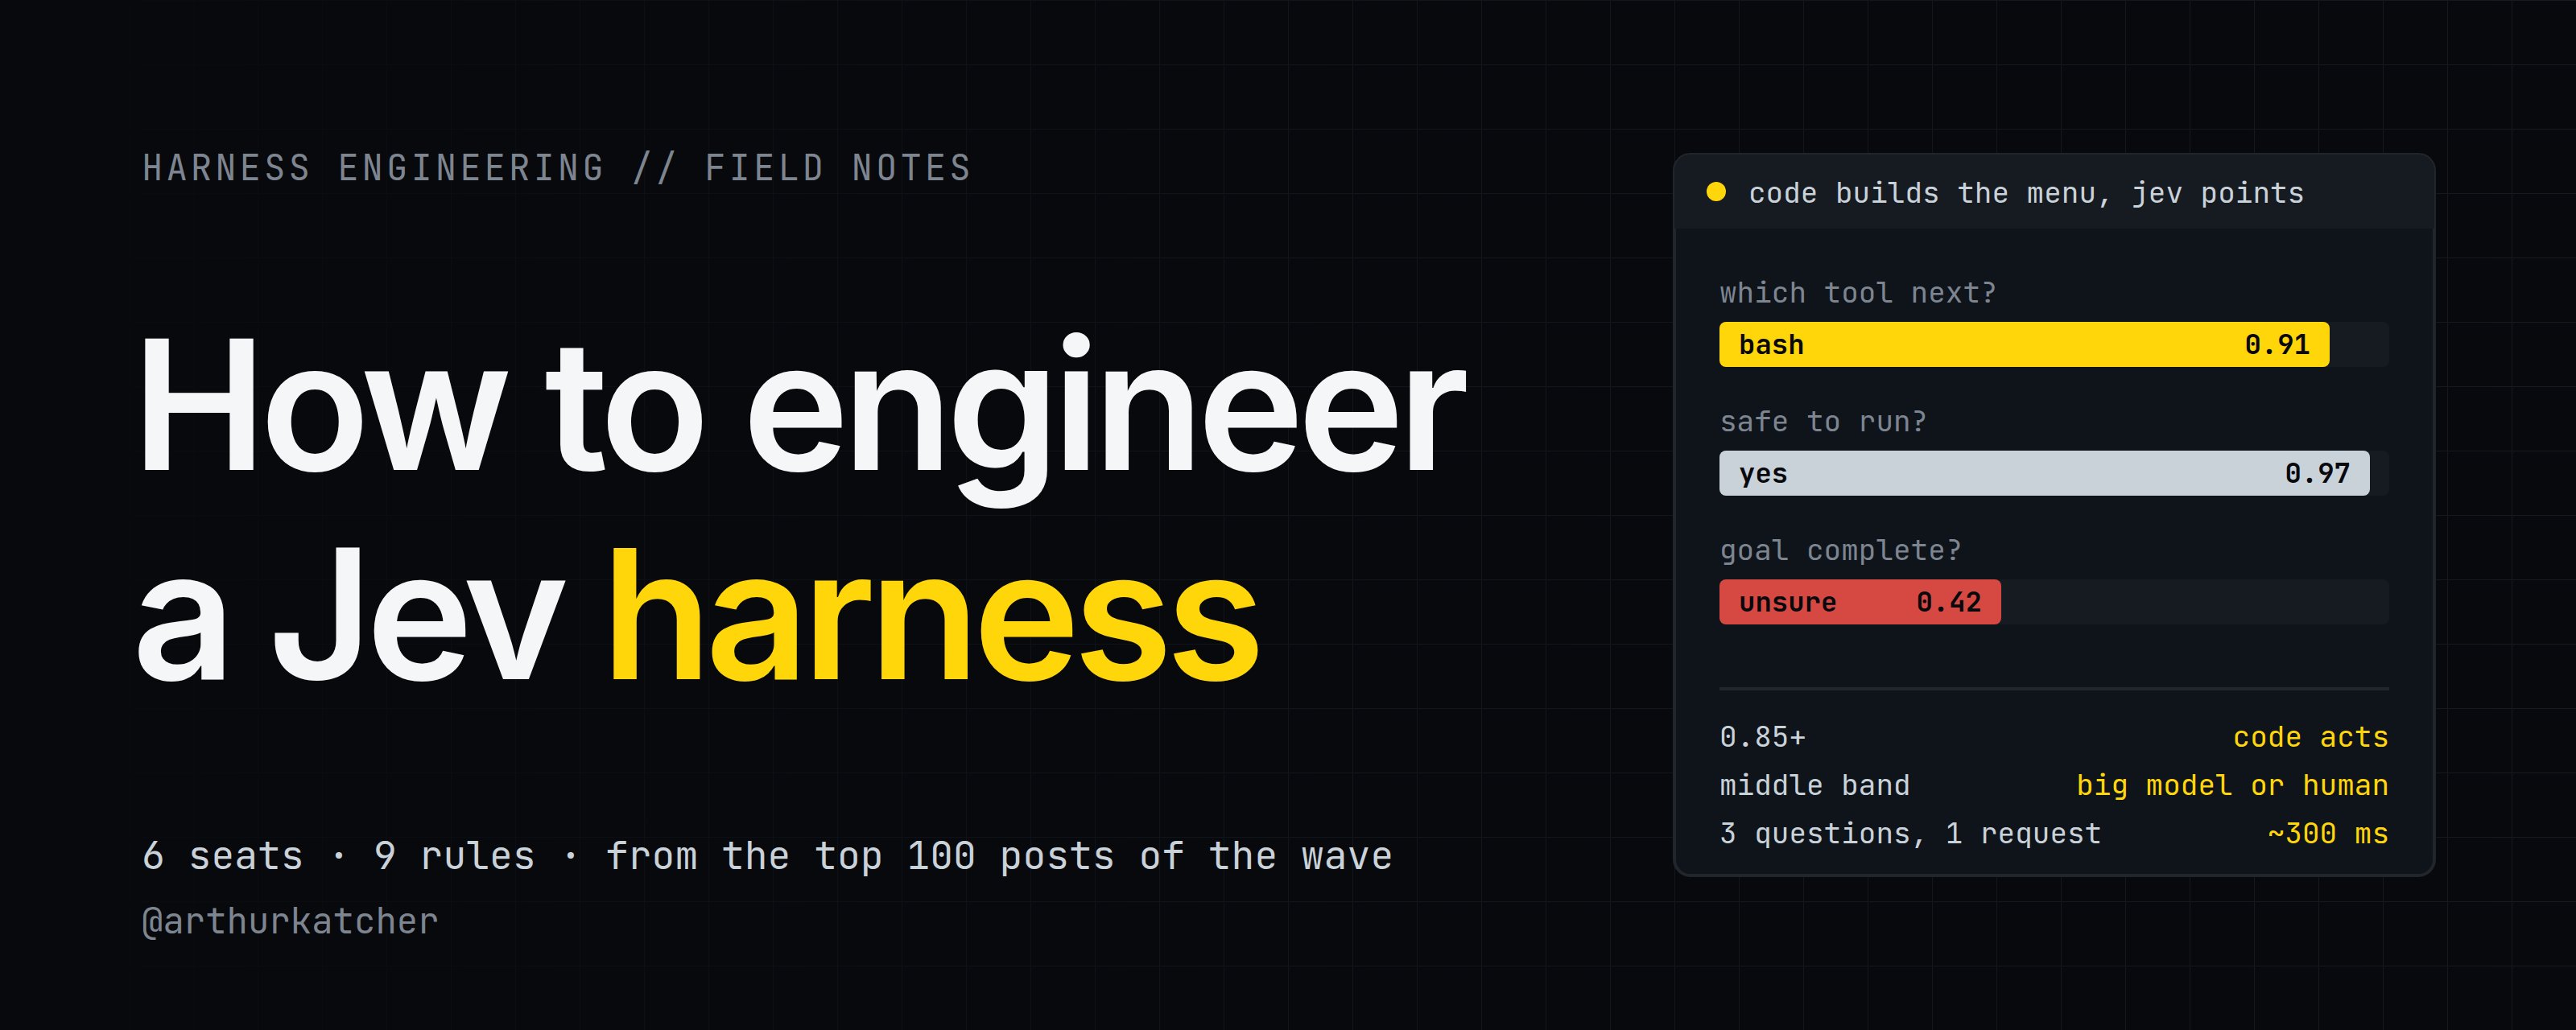
How to engineer a Jev harness

I went through how people actually wire Jev into their agents: where it sits in the loop, what they feed it, and when they stop trusting it.

· 9 min read

05.

Terminal UIs for Harnesses in 2026: who builds on what, and why

We spent forty years escaping the command line. Then AI agents arrived, and the best-funded interface teams in software went back to a grid of monospaced characters.

· 9 min read

06.

AI Agent Security in 2026: Why Hooks Are the New Firewall?

The problem we solved in operating systems years ago rises again with AI agents. A four-property framework for AI agent security in 2026.

· 13 min read

X
GitHub